

A case file is like a safe filled with private, personal information: names, addresses, family relationships, and financial status. As the judiciary digitizes case files and integrates artificial intelligence (AI) to assist judges, the primary question is not "how capable is the AI?" but rather, "is my data secure?"
This is the "judicial data paradox": while centralizing data makes it easier to search and utilize, it also renders the information highly sensitive if not protected correctly. With nearly 700,000 cases handled annually—each containing the private details of the parties involved—centralizing this data helps alleviate the burden on judges; however, even a minor security lapse could simultaneously compromise a vast number of individuals.
Security concerns regarding the integration of case data into AI systems
These concerns are well-founded. When case files are incorporated into an AI system, three primary risks often arise:
● Data falling outside of one’s control: If an AI system operates on external, public infrastructure, case information could potentially pass through environments beyond the judiciary’s oversight.
● Unauthorized access: When data is consolidated in a single location, a vulnerability in access controls could expose multiple cases at once, rather than just an isolated instance.
● Inadvertent disclosure through AI-generated responses: There is a risk that sensitive details from one case could inadvertently appear in the output provided for an entirely different case.
Such concerns cannot be resolved through mere promises. They can only be addressed by ensuring that security is integrated into the system from the very design phase.
Data Protection Principles: Authorization and Access Control
An AI system designed for the courts must be built upon the following core principles:
● Operation on dedicated infrastructure: Data is processed within the Supreme People’s Court’s own private data infrastructure, independent of external public services.
● Role-based and scope-based authorization: Staff members and judges are granted access only to case files that fall within their specific jurisdiction or scope of work.
● Access monitoring and auditing: Every instance of viewing or editing a case file is logged, allowing for subsequent review when necessary.
● Data isolation between cases: Information from one case must not "spill over" into the results or context of another case.
● Verifiable, source-backed responses: The system prioritizes retrieving information from the Court’s internal database before extending its search to designated, authoritative websites. All responses include citations, enabling users to verify the information independently.
● AI-assisted, judge-led decision-making: Any suggestions provided by the system serve solely as a reference; the final authority rests with the judge and the trial panel.
Judgment Anonymization Feature: Automatic redaction of personal, corporate, and geographical information prior to publication
Internal data security is only half the story; the other half concerns the point at which a judgment is released to the public.
In accordance with Resolution No. 03/2017/NQ-HĐTP, judgments anonymized pursuant to Article 7 ensure the protection of personal and family privacy when published on the Court’s electronic portal. Sensitive information is replaced by Vietnamese letters (A, B, C, etc.)—optionally combined with unique, non-repeating, and unambiguous numerical identifiers—ensuring that the substance of the judgment remains unchanged. Judgments from closed-door trials are not made public.
Previously, the process of redacting sensitive information—identifying and masking names and addresses within each judgment—was performed manually. Given the hundreds of thousands of cases handled annually, this method was not only time-consuming but also prone to oversight.
An automated redaction feature addresses this bottleneck through a three-step process:
● Step 1: Identification of information to be masked. The system scans the text to detect personal names, business names, geographical locations, and other potentially identifying data.
● Step 2: Replacement with consistent placeholders. Each entity is assigned a fixed, unique identifier throughout the judgment, allowing readers to follow the roles of the respective parties.
● Step 3: Final review before publication. Authorized personnel verify the output; while the system minimizes errors, the ultimate responsibility remains with human reviewers.
Balancing the publication of judgments with the protection of privacy
Public access to judgments enables societal oversight and ensures consistency in legal interpretation across different court levels. Privacy protections, meanwhile, safeguard individuals after a case has concluded, preventing them from facing undue scrutiny or stigma simply because they were once involved in legal proceedings. The balance lies in disclosing the substance of the trial—the facts, legal arguments, and the legal basis—while replacing personally identifiable information with placeholders.
As the judiciary moves toward a fully digital operational model by 2027, data can only truly serve as an asset if the public trusts that their personal information is kept secure.
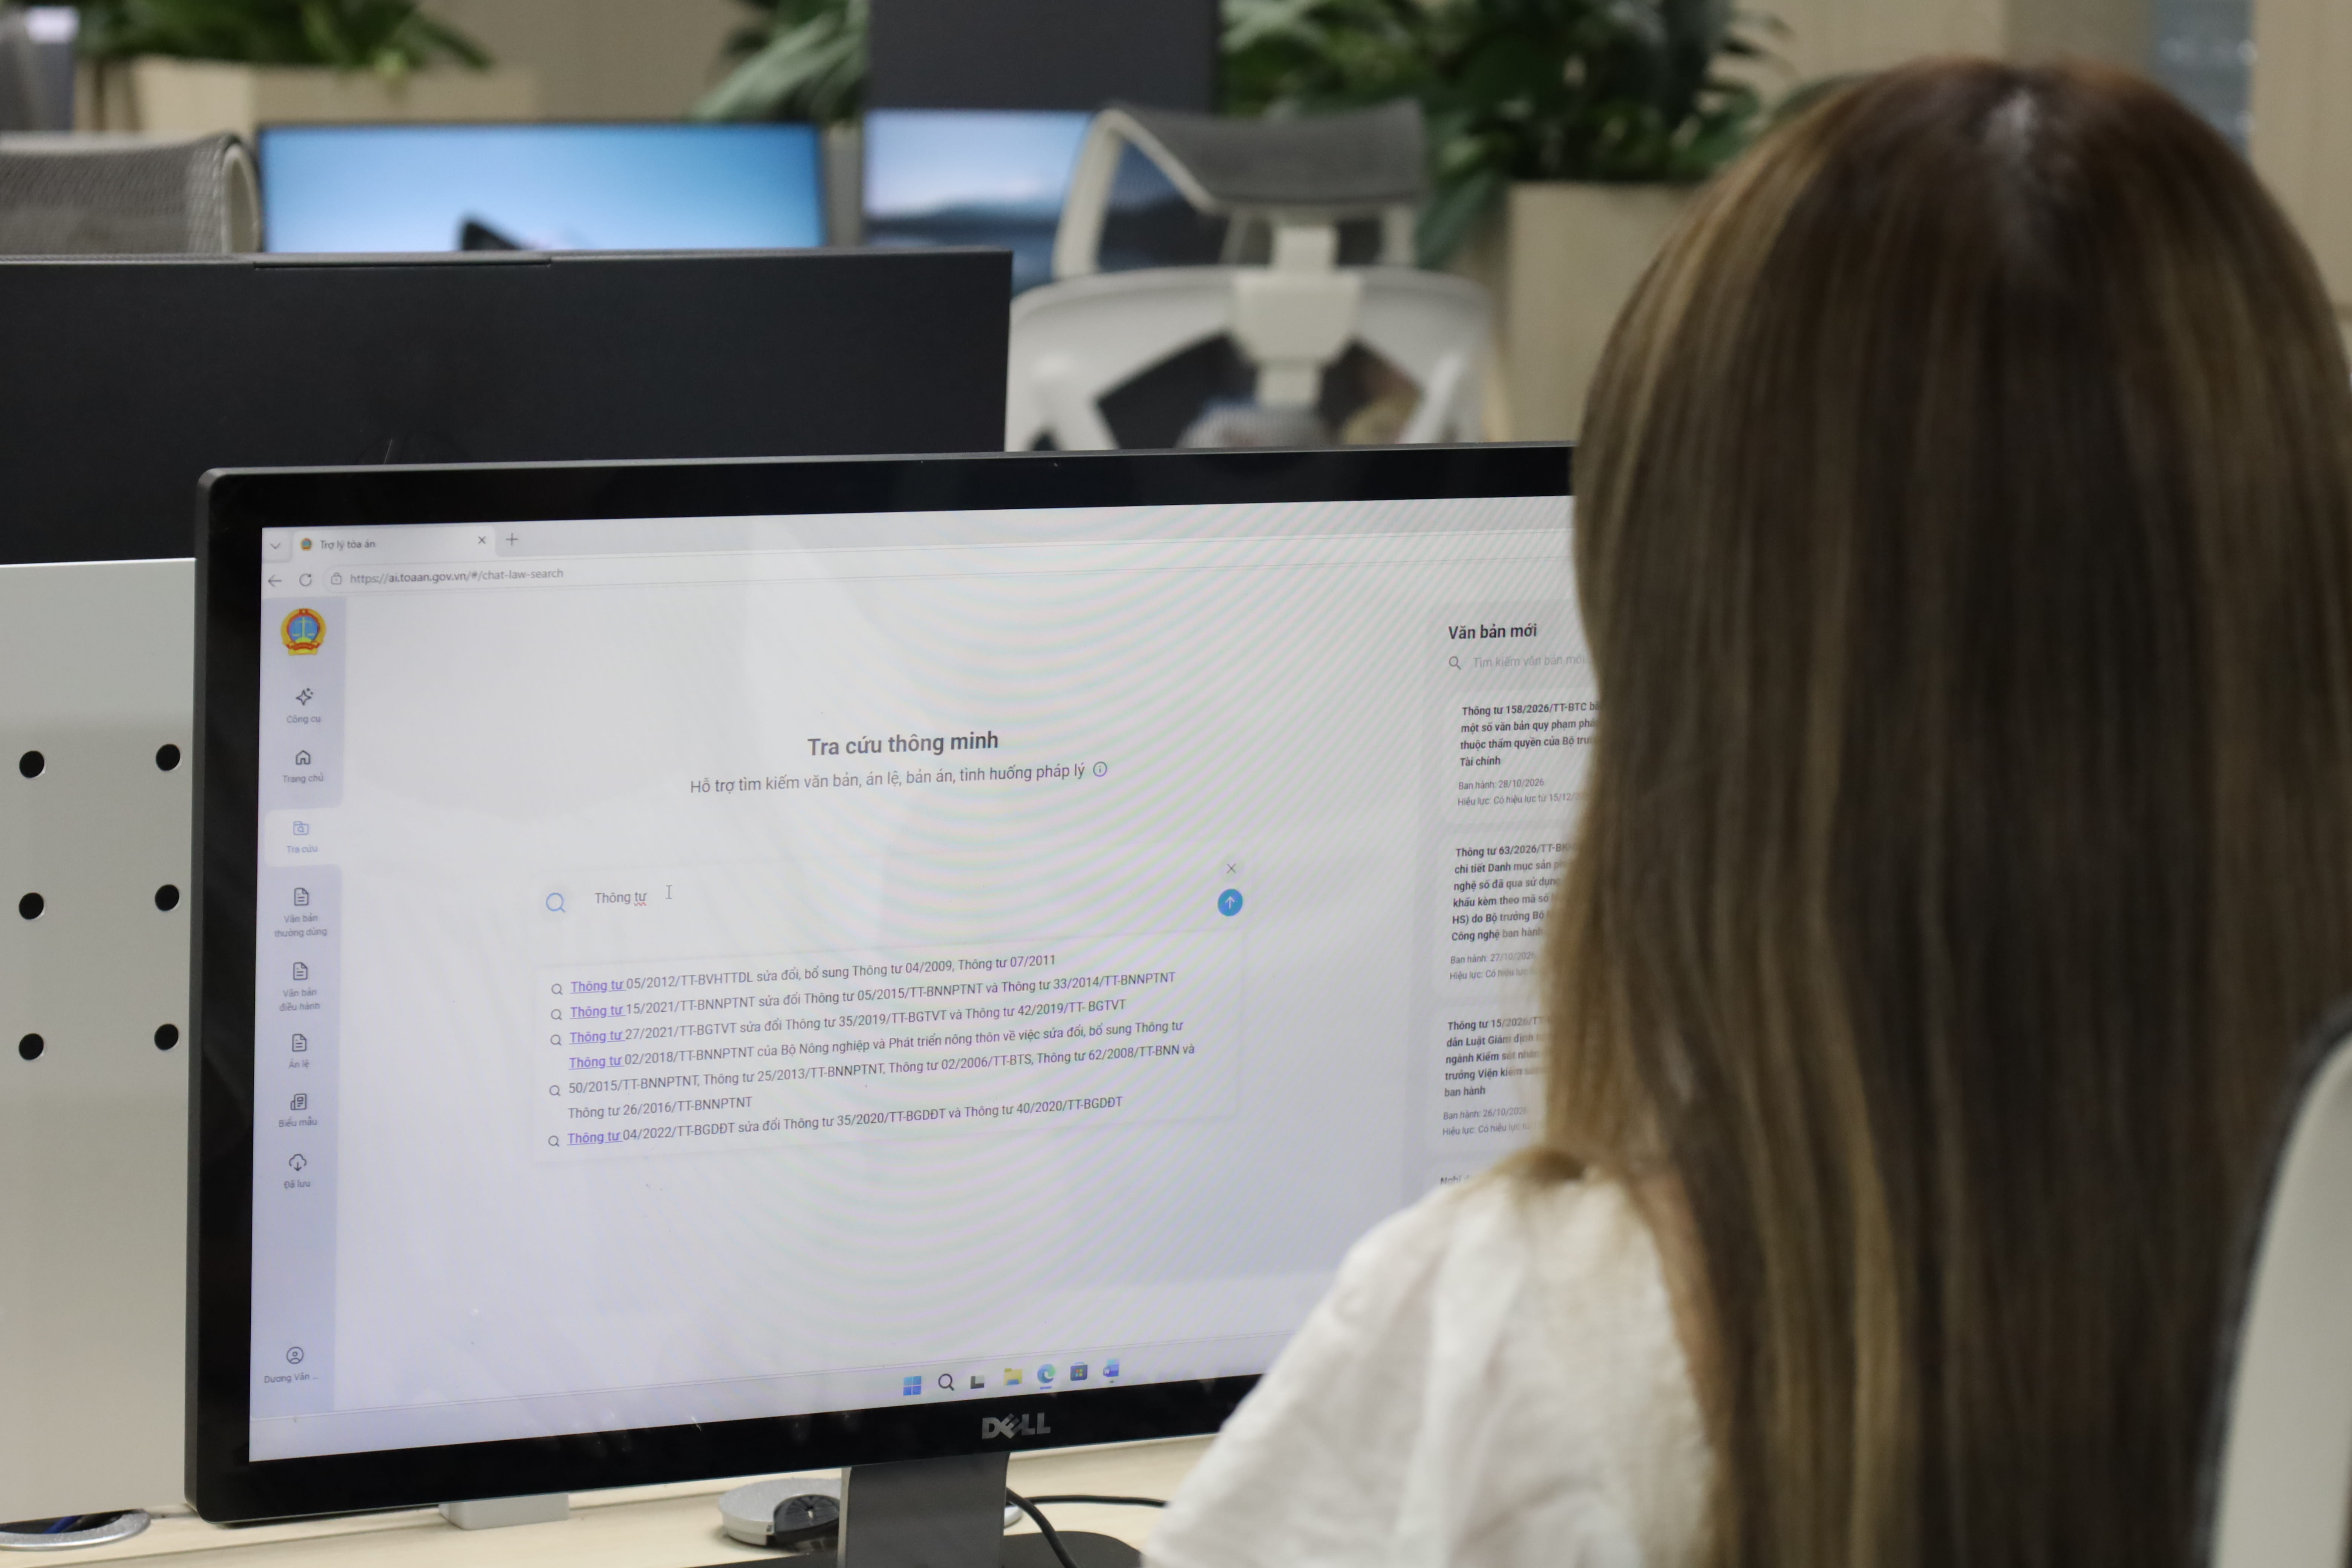
In support of this objective, the "Court Virtual Assistant"—an AI application developed by the Supreme People's Court in collaboration with Viettel AI—is currently being integrated into the pilot platform for end-to-end case management. The assistant supports judges in conducting research, reviewing case files, and drafting legal documents—utilizing a database of over 1 million judgments and decisions, alongside 160,000 legal texts, all hosted on the Supreme People’s Court’s own infrastructure—thereby granting those who preside over the law more time to deliver impartial, fair, and well-reasoned rulings.
Other news


 Hotline: +84 98 1900 911
 Email: viettelai@viettel.com.vn
 Epic Building, 19 Duy Tan Street, Cau Giay District, Hanoi.
23rd Floor, Viettel Complex Building, 285 Cach Mang Thang Tam, Hoa Hung Ward, Ho Chi Minh City.